Day 29
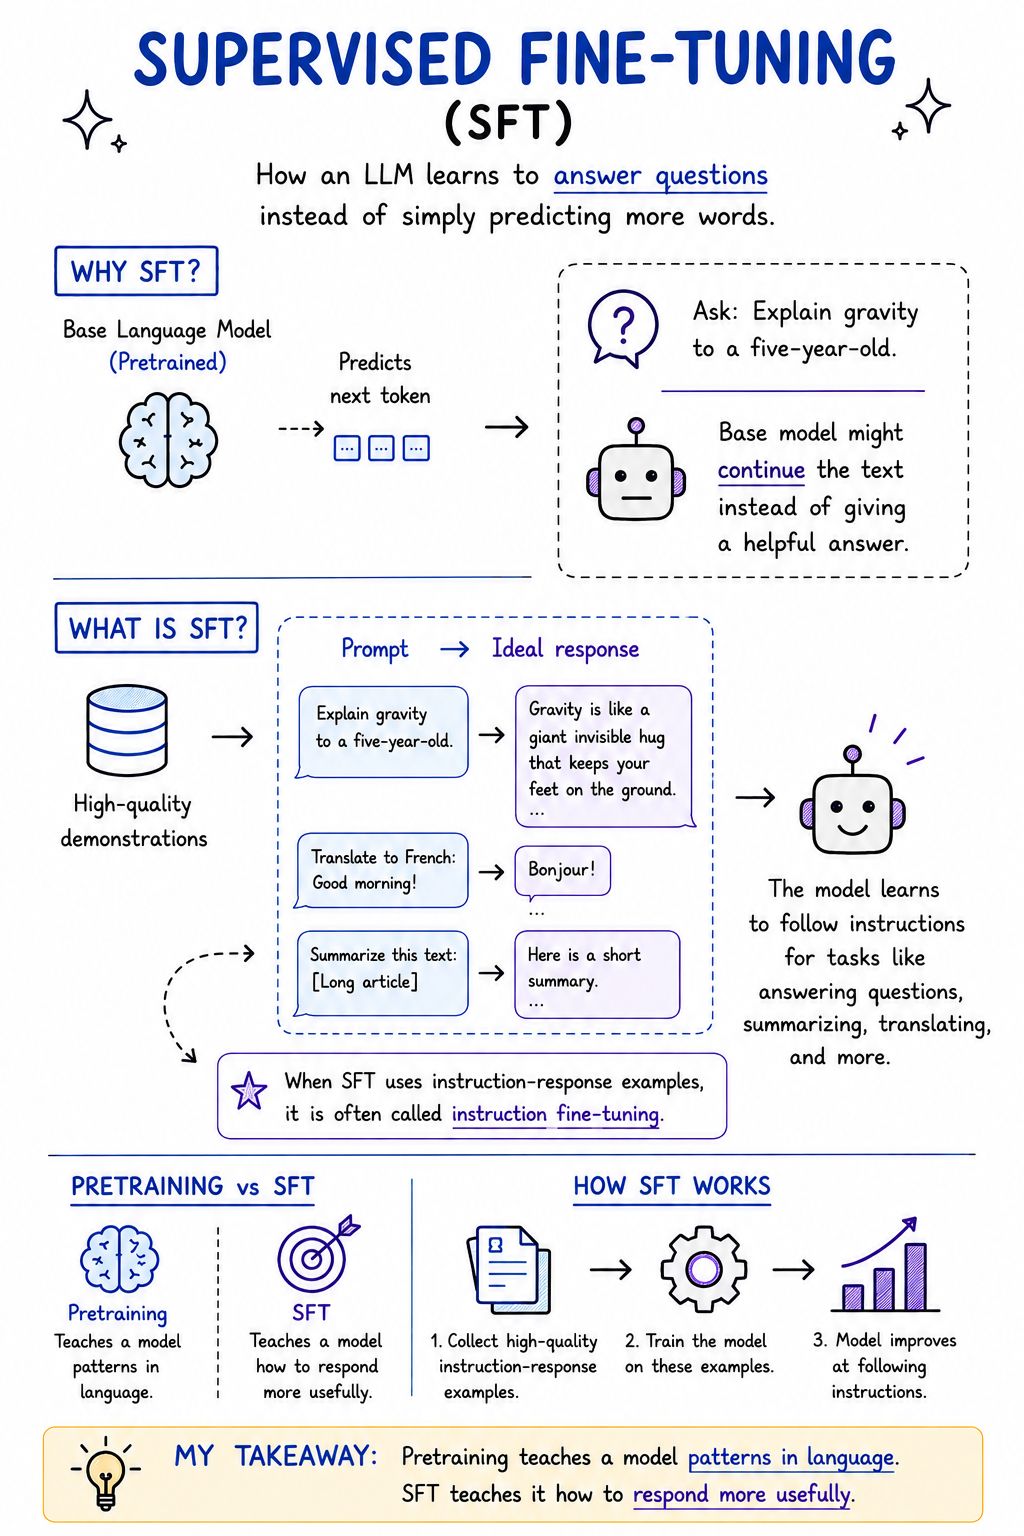
Ever wondered how an LLM learns to answer questions instead of simply predicting more words?
Today, I learned about Supervised Fine-Tuning (SFT).
Many base language models are pretrained to predict the next token. This gives them broad language capabilities, but it does not automatically make them good at following instructions.
For example, ask: Explain gravity to a five-year-old.
A base model might continue the text instead of providing a helpful answer.
SFT trains the model using high-quality demonstrations:
Prompt → Ideal response
These examples show the model how to answer questions, summarize text, translate languages, and perform other tasks.
When SFT uses instruction-response examples, it is often called instruction fine-tuning.
My takeaway:
Pretraining teaches a model patterns in language.
SFT teaches it how to respond more usefully.
Day 29 of 1% better.
LinkedIn post: https://lnkd.in/p/gg3DEgFT (opens in a new tab)